

CAMLIS 2026
DAY ONE
Keynote: AI Security: A 10+-year Perspective
Speaker: David Evans, Olsen Bicentennial Professor of Engineering and Professor of Computer Science, University of Virginia
Abstract: David Evans traces more than a decade of AI security research against a longer history of security automation. Early work on network intrusion detection and evasive PDF malware illustrates how difficult it is to test whether defenses will hold up when attackers adapt. He reviews the progress made in evaluating adversarial robustness and connects those lessons to the security of today’s AI agents.
As agents accelerate vulnerability discovery and exploitation, Evans argues that teams need to reduce exposure before attacks occur. He discusses how permission settings and user incentives shape the security of agentic systems, and why people remain accountable for decisions about deployment and oversight.
The talk closes by putting technical exploits in context. Configuration errors and abuse of intended functionality account for much of the harm users experience. The discussion considers how AI could help defenders find and fix vulnerabilities and prevent abuse.
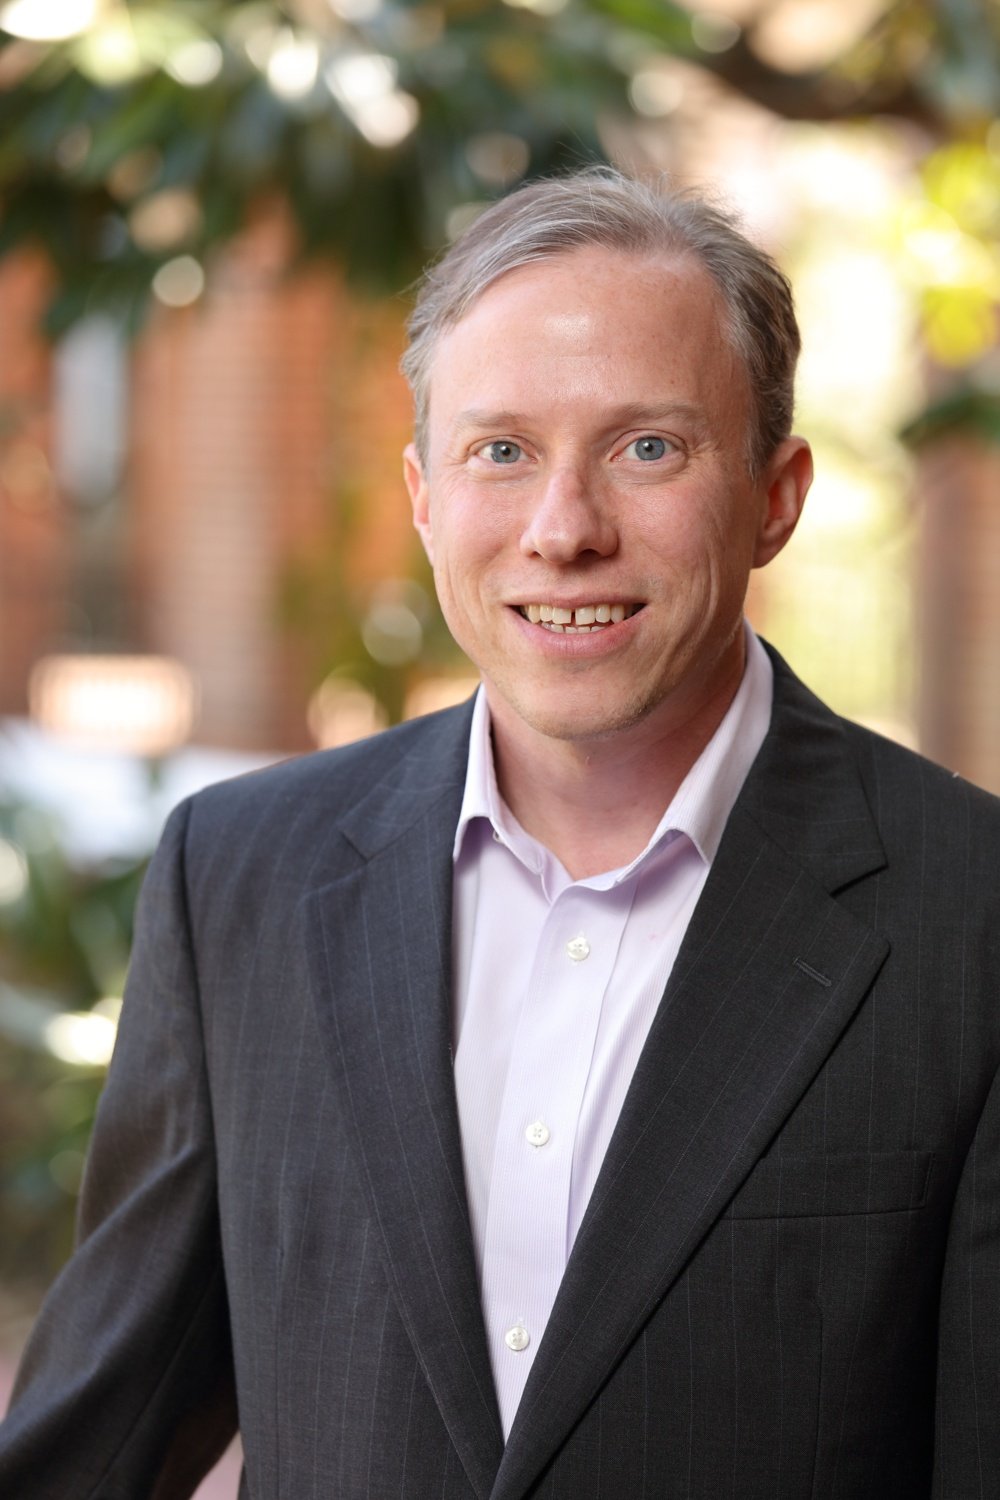
David Evans
Olsen Bicentennial Professor of Engineering and Professor of Computer Science, University of Virginia
-
Speaker: Arjun Chakraborty
Author(s): Arjun Chakraborty, Sandra Ho, Adam Cook
Abstract: CTI-REALM puts AI agents in the role of a detection engineer. Agents interpret threat reports, inspect schemas, query telemetry and write rules for emulated attacks across Linux, cloud services and Kubernetes. The benchmark checks whether the resulting rules detect the attacks and also scores the steps agents take, making it possible to compare models and test the contribution of tools and memory.
-
Speaker: John Seymour
Author(s): John Seymour, Mario Moreno, Matt Rittinghouse
Abstract: Security analysts and agents need to know what telemetry exists before they can query it effectively. Citadel maintains a Git-backed inventory that pairs readable descriptions of log sources with facts that can be checked automatically. The talk reports how the system was deployed across three production log platforms and examines adoption, operating cost and which parts of the catalog remain reproducible when rebuilt.
-
Speaker: Diane Lin
Author(s): Dianhuan Lin, Zicun Cong
Abstract: A security agent can give conflicting answers to the same ambiguous alert, especially when the input sits close to its decision boundary. The presenters treat this inconsistency as an attack surface. They combine explicit security knowledge with retrieved examples from past cases and report that the resulting system makes fewer conflicting decisions and is harder to manipulate with boundary-search attacks.
-
Speaker: Wayne Fullen
Author(s): Ayush Garg, Sophia Hager, Jacob Montiel, Aditya Tiwari, Michael Gentile, Zach Reavis, David Magnotti, Wayne Fullen
Abstract: RuleForge generates candidate detection rules from Nuclei templates for newly disclosed web vulnerabilities. It uses synthetic tests and a language-model judge to check whether each rule detects exploitation without flagging legitimate traffic. The talk describes how the rules are refined, how analyst feedback is incorporated, and how the validation method reduced false positives in production compared with relying on synthetic tests alone.
-
Speaker: Edward Raff
Author(s): Edward Raff, Aditya Kapoor
Abstract: Malware authors can falsify executable compile timestamps, making them unreliable for building chronological training and test sets. Using EMBER2024, this study asks whether a model can estimate when a file was first observed or identify a misleading timestamp. It finds that predicting the first-seen date is difficult, while detecting unreliable compile timestamps is a more promising task.
-
Speaker: Elad David
Author(s): Elad David, Max Fomin
Abstract: Ordinary typos can leave a language model’s answer essentially unchanged while disrupting a prompt-injection detector that reads the model’s hidden states. The authors measure how this effect travels across token positions and compare detectors that aggregate information across those positions. A fixed suffix lets a single-position probe read beyond the affected tokens and recovers most of the lost detection performance.
-
Speaker: David Ion
Author(s): David Ion, Pradeep Swain, Edward Raff, Daniel Chipiristeanu
Abstract: Trend Micro’s locality-sensitive hash is useful for finding near duplicates, but its distance function does not satisfy the properties many indexing and machine-learning methods require. This talk presents a deterministic mapping of TLSH digests into Euclidean space. The mapping keeps approximate similarity scores while making the digests usable with standard tools that require a metric distance.
-
Speaker: Ryan Fetterman
Author(s): Ryan Fetterman
Abstract: A fine-tuned classifier may perform well on conventional test data while misclassifying malicious PowerShell scripts after edits that leave their behavior intact. Comparing a base model with its security-tuned counterpart, Fetterman traces decisions to an attention circuit inherited from the base model. The talk shows how fine-tuning changes what the circuit responds to and proposes checks for prioritizing variants to test before deployment.
DAY TWO
Keynote: AI Security and the Future of Responsible Innovation
Speaker bio > | GOV.UK profile
Speaker: Henry de Zoete OBE, Director of the UK AI Security Institute and Visiting Fellow at the University of Oxford
Session overview: This keynote addressed the role of AI security in responsible innovation. De Zoete brought experience from advising the UK prime minister on AI, helping establish the AI Security Institute, and leading preparations for the Bletchley Park AI Safety Summit. He also served as the UK’s co-lead negotiator for the AI Seoul Summit.
The UK AI Security Institute’s work on evaluating advanced AI systems provides public background for the session. Explore the institute’s research >

Henry de Zoete OBE
Director of UK’s AI Security Institute and former advisor in the Department for Science, Innovation and Technology. Visiting fellow to the Oxford Martin AI Governance Initiative and Said Business School at the University of Oxford.
-
Speaker: Paul Urian
Author(s): Paul Urian, Cosmin Alexa, Donato Onofri
Abstract: The researchers used an AI coding agent to investigate three open-source coding agents and reported 20 vulnerabilities, four of which received CVE identifiers. The findings included remote code execution and credential exposure. The talk explains the research workflow and describes recurring conditions that made these bugs consequential, including permissive defaults, weak trust boundaries and unsandboxed execution.
-
Speaker: Ganni Galea Curmi
Author(s): Giovanni Galea Curmi, Ben Wilde
Abstract: The study compares 12 language models on a production codebase whose vulnerabilities were undisclosed at the time of scanning. The researchers vary the tools and context provided by the agent harness and validate the findings to compare coverage and cost. They find that models discover different vulnerabilities, so the choice of harness and model depends on the coverage sought and the resources available.
-
Speaker: Blake Bullwinkel
Author(s): Blake Bullwinkel, Eugenia Kim, Amanda Minnich, Mark Russinovich
Abstract: The authors train attacker and defender models in stages using Group Relative Policy Optimization. Training progresses from single- and multi-turn attacker tasks to alternating updates for both models, with multiple judging criteria to balance competing objectives. The resulting attacks transfer to other models and the defenders retain general utility, although the authors observe that attacker diversity can fall during training.
-
Speaker: Muqeet Ali
Abstract: An attacker model proposes prompts that consume disproportionate resources on a target language model, and a separate refiner iteratively improves them. The talk compares effects across several target models, measuring both latency and output length. In the reported tests, compact prompts that resembled ordinary requests produced substantial increases in response time and generated tokens.
-
Speaker: Devin Robison
Author(s): Devin Robison, Hsin Chen, Jasmine Jaksic, Ashley Song
Abstract: Nomos evaluates privileged agent actions before execution. It combines deterministic policies with risk assessments from multiple models, then signs approved actions with single-use authorizations limited in time and scope. The talk reports how the system handled benign and adversarial requests in Kubernetes administration, pull-request management and security-alert triage, including the trade-off between blocking attacks and approving legitimate actions.
-
Speaker: Elia Nikolaou
Author(s): Elia Nikolaou, Magnus Wiik Eckhoff, Robert Flood, Gudmund Grov, Vasileios Mavroeidis, David Aspinall
Abstract: CaMeLoT checks an agent’s entire plan before it calls external tools. It converts the plan into a finite-state model that records tool calls and where their data came from. A model checker verifies temporal policies for security and progress and returns a counterexample when a policy fails, so an unsafe workflow can be rejected or corrected before execution.
-
Speaker: Aryan Luthra
Author(s): Anna Bertiger, Bobby Filar, Aryan Luthra, Siddharth Arya, Kshitij Jain
Abstract: Operational security teams often lack labeled benchmarks for judging whether an agent’s memory and feedback mechanisms help. This study uses a stronger teacher model to give sparse corrections to a smaller student. Across several security tasks, progress toward the teacher correlated with improvement on held-out labels, offering a way to compare learning harnesses when gold-standard answers are unavailable.
DAY THREE
-
Speaker: Tamás Vörös
Author(s): Tamás Vörös
Abstract: NXDirection detects a direction in language-model activations associated with treating text as instructions. At inference time, it suppresses that signal for tokens from untrusted sources. The talk reports results across nine models on two prompt-injection benchmarks, measuring how much the intervention reduces attack success and how much ordinary task performance it preserves.
-
Speaker: Mihai Nechita
Author(s): Daniel Chipiristeanu, Mihai Nechita, Denis Rozimovschii
Abstract: The researchers benchmark how behavior-preserving file changes can evade production malware classifiers. The evaluation covers executables, PDFs, scripts and memory buffers. A modular framework combines modifications to reveal weaknesses by detector and file population. The talk also presents a covariate-shift correction to improve robustness without building a large adversarial training corpus.
-
Speaker: Andy Hsu
Author(s): Andy Hsu, Konstantin Berlin
Abstract: Privacy benchmarks disagree on what counts as an identifier, so a detector can score well while missing disclosures that matter in practice. The authors define explicit criteria for 12 categories and use them to relabel about 1.1 million examples. They train a compact encoder and compare it under both the unified and original labeling policies, showing that benchmark rankings can change with the definition.
-
Speaker: Mahmoud Abdelfattah
Author(s): Mahmoud Abdelfattah, Hamid Nasiri, Peter Garraghan
Abstract: kNNGuard detects unsafe, off-topic or adversarial prompts using hidden activations from an existing language model and a small bank of labeled examples. It combines nearest-neighbor evidence from multiple layers with embedding similarity. The authors compare it with fine-tuned guardrails across six domains and report competitive detection with faster inference and no model retraining when the domain changes.
Additional Content
-
Poster session · Thursday, October 22, 2026
A Large-Scale Sanitized Dataset of Windows API Behavioral Reports from VirusShare Malware
Aaron Walker
View poster PDFA Perplexity-Aware Perturbation Approach to Guard Against Prompt Injection Attacks
Muqeet Ali
View poster PDFAlignment of Autonomous Cyber Defense Agents via Adaptive Policy Shaping
Dena Mujtaba, Bharadwaj Ravichandran, Brian Hu, Arslan Basharat
View poster PDFAttnDA: Attention-Based Classification for Indirect Prompt Injection
Amelia Kawasaki, Stefan Lee
View poster PDFAutomated Adversarial Testing for LLMs: Guided Fuzzing and Browser-Native Red Teaming
Daniel Chipiristeanu
View poster PDFBeyond Success Rate: Cost-Aware Evaluation of Offensive and Defensive Security Agents
Paul Kassianik, Blaine Nelson, Yaron Singer
View poster PDFDetection as Geometry: On-Device Semantic Policy Enforcement via Signed Directional Alignment
Ajaya Neupane, Ruslan Vaulin, Kurtis Shelton
View poster PDFEvaluating LLM Security Review Agents with Operationally Sourced Ground Truth
Karim Liman-Tinguiri, Mudita Khurana
View poster PDFLLM-PassEval: A Practical Framework for Evaluating LLM-Assisted Passphrase Generation
Siddharth Das Sarkar, Supriya Khadka, Sanchari Das
View poster PDFOperationalizing Enterprise AI Security: An Open-Source Framework for AI Cyber Risk Management
Josh Harguess, Chris M. Ward, Eric Cardinal
View poster PDFScopeJudge: Cost-Aware Pre-Execution Gating for Offensive Security Agents
Shane Caldwell, Max Harley, Ads Dawson, Michael Kouremetis, Vincent Abruzzo, Will Pearce
View poster PDFSecret Scanner Agent: Extracting Secrets and Access Context from Unstructured Documents
Zixiao Chen, Mariko Wakabayashi, Charlotte Siska
View poster PDFShow, don’t tell: Calibrating Agentic SOC Analysts via Hierarchical Evidence Graphs
Tamas Nyiri
View poster PDFTemporal Splitting with Near-Duplicate Samples: Measuring Memorization versus Generalization in Malware Classification
Michael Slawinski, Amine Boubezari, J.P. Clark
View poster PDFTRACE: Threat Recognition through Administrative Correlation and Extraction
Mark Paes
View poster PDFTraining-Free Refusal of MCP Exploits via Retrieval-Augmented Generation
John T. Halloran
View poster PDFWorkspace Topology as an Attack Vector in Agentic Coding Assistants
Alexandre G. R. Day, Pradeep Yadlapalli, Sriram Venkatapathy, Thomas Paniagua, Nick Raines, Sahil Wadhwa, Himanshu Kumar, Andy Luo, Sudeep Panyam, Rikhiya Ghosh, Pranab Mohanty, Giri Iyengar
View poster PDF